\(K\)-means algorithm we provide is a wrapper to the Armadillo's k-means routine. Two types of initialization schemes are employed. Please see the parameters section for more details.
kmeans(data, k = 2, ...)Arguments
- data
an \((n\times p)\) matrix of row-stacked observations.
- k
the number of clusters (default: 2).
- ...
extra parameters including
- init
initialization method; either
"random"for random initialization, or"plus"for k-means++ starting.- maxiter
the maximum number of iterations (default: 10).
- nstart
the number of random initializations (default: 5).
Value
a named list of S3 class T4cluster containing
- cluster
a length-\(n\) vector of class labels (from \(1:k\)).
- mean
a \((k\times p)\) matrix where each row is a class mean.
- wcss
within-cluster sum of squares (WCSS).
- algorithm
name of the algorithm.
References
Sanderson C, Curtin R (2016). “Armadillo: A Template-Based C++ Library for Linear Algebra.” The Journal of Open Source Software, 1(2), 26. ISSN 2475-9066.
Examples
# -------------------------------------------------------------
# clustering with 'iris' dataset
# -------------------------------------------------------------
## PREPARE
data(iris)
X = as.matrix(iris[,1:4])
lab = as.integer(as.factor(iris[,5]))
## EMBEDDING WITH PCA
X2d = Rdimtools::do.pca(X, ndim=2)$Y
## CLUSTERING WITH DIFFERENT K VALUES
cl2 = kmeans(X, k=2)$cluster
cl3 = kmeans(X, k=3)$cluster
cl4 = kmeans(X, k=4)$cluster
## VISUALIZATION
opar <- par(no.readonly=TRUE)
par(mfrow=c(1,4), pty="s")
plot(X2d, col=lab, pch=19, main="true label")
plot(X2d, col=cl2, pch=19, main="k-means: k=2")
plot(X2d, col=cl3, pch=19, main="k-means: k=3")
plot(X2d, col=cl4, pch=19, main="k-means: k=4")
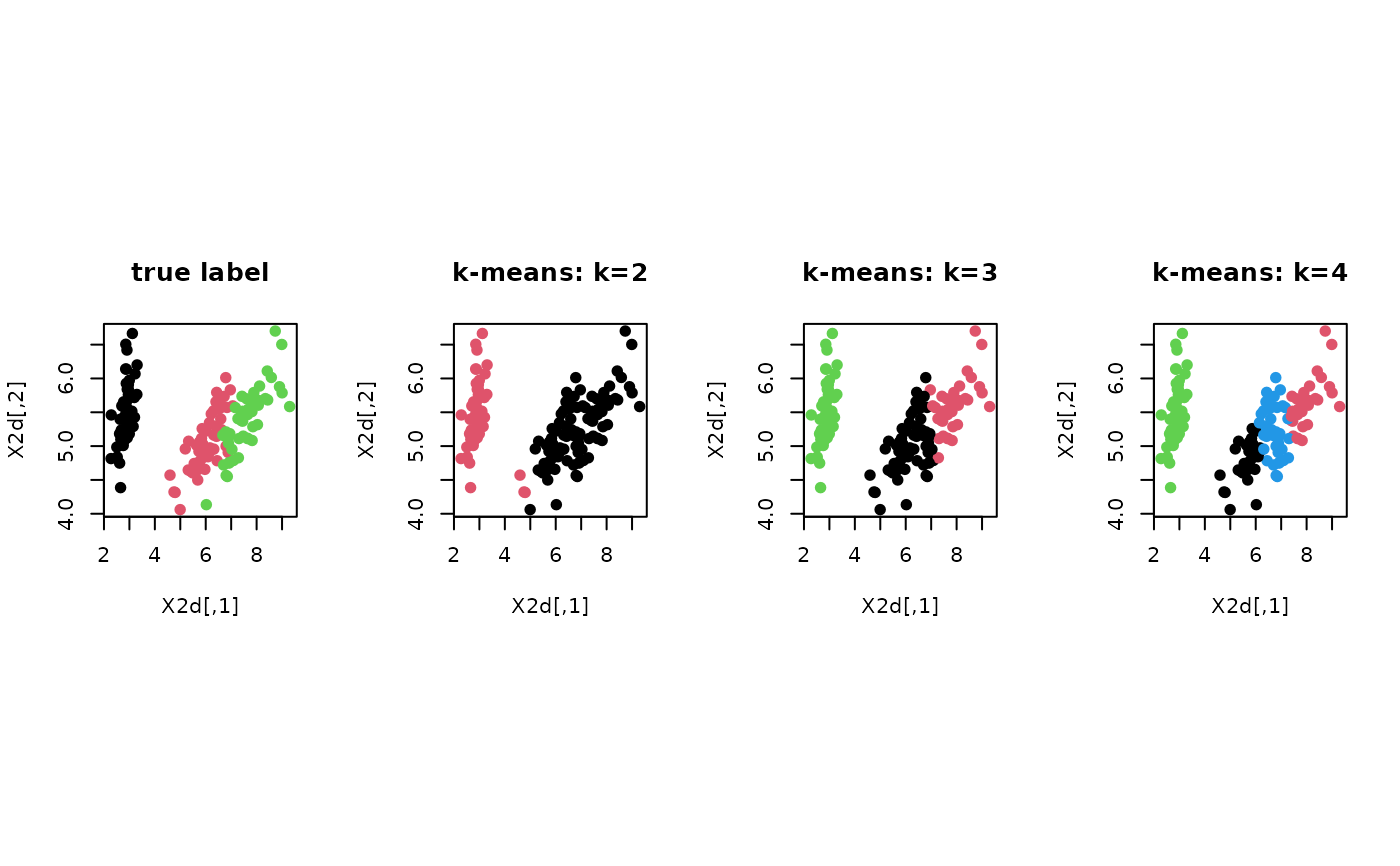 par(opar)